GPU rental · request capacity
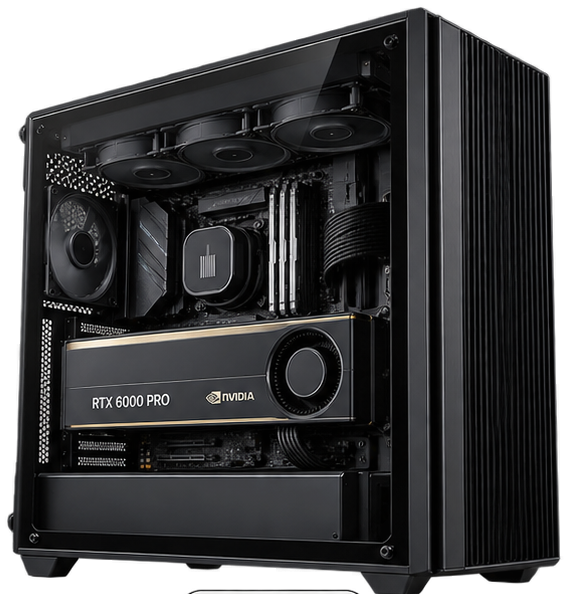
NVIDIA's Blackwell workstation-class card with 96 GB of GDDR7, as a dedicated EU-hosted AxForge machine. Request dedicated capacity for this GPU through AxForge. Registered demand is used to prioritize new capacity.

Specifications
| Card | NVIDIA RTX 6000 Pro |
|---|---|
| Memory | 96 GB GDDR7 |
| Class | Blackwell workstation class |
| Availability | Request capacity: register your requirement in the console |
| Tenancy | Dedicated machine, your traffic only, full SSH access |
| Pricing | Quoted per deployment |
| Region | European region, placement confirmed with your request |
Fit
| Use case | Why it fits |
|---|---|
| Large-context inference | 96 GB leaves room for long KV caches next to the model weights. |
| Fine-tuning small models | Enough memory to train small models on a single dedicated card. |
| Image / video generation | Workstation-class card with headroom for generation pipelines. |
Community data
On the one benchmark that runs identically across NVIDIA cards, the RTX 6000 Pro decodes at 274.2 t/s with 14,855 t/s prompt processing, about 3.6× an RTX 3060. An RTX 5090 is actually a touch faster single-stream on a small model (290 t/s). That is not the point of this card.
Same-workload numbers from the llama.cpp CUDA scoreboard (Llama 2 7B Q4_0, tg128, full GPU offload). Community measurements, not ours. Full ladder on the GPU catalogue.
Community data
GamersNexus ran the same LM Studio workloads on an RTX 4090, RTX 5090 and RTX 6000 Pro. Small models: the cards are close. Models that crowd 24 to 32 GB: the consumer cards start spilling out of VRAM and collapse, while 96 GB keeps the whole model on the GPU.
| Model | RTX 4090 · 24 GB | RTX 5090 · 32 GB | RTX 6000 Pro · 96 GB |
|---|---|---|---|
| DeepSeek Llama 8B Distil | ~62 t/s | ~81 t/s | ~81 t/s |
| Phi-4 8-bit | ~43 t/s | ~51 t/s | 62 t/s |
| Qwen 2.5 | ~32 t/s | ~35 t/s | 44 t/s |
| InternLM | ~12 t/s | ~40 t/s | 50 t/s |
| Mistral Small (~26 GB) | 6.4 t/s | 17 t/s | 42.4 t/s |
| Gemma 3 27B | ~4 t/s | ~5 t/s | 29 t/s |
| Llama 3.3 70B Q4 | very low | very low | vastly faster |
The RTX 6000 Pro is not 6× faster silicon. It simply never has to offload. That makes it a different class of card: large models entirely on one GPU, with workstation-class bandwidth behind them. Approximate figures (~) read from the source's charts.
vs RTX 5090
The 5090 is the fastest-per-euro choice for models that fit in 32 GB. This card is for the models that don't.
vs DGX Spark
DGX Spark holds even more (128 GB unified) and is available now from €0.85/hour, but at ~273 GB/s bandwidth: capacity first, decode speed second. This card gives you both.
Data & privacy
Like every AxForge machine: your model, your traffic, our hardware. Prompts are never persisted. Only request metadata (token counts, timestamps, status) is kept for billing and operations. Full policy at axforge.ai/privacy.
Models
Estimated from each model's own files and config (96 GB on one card): language models · image models · video models · embedding models.
FAQ
Request dedicated capacity for this GPU through the AxForge Console: Ask for this GPU. Registered demand is used to prioritize new capacity, and machines are sized to the workloads that asked for them. Dedicated DGX Spark (GB10) capacity is available now from €0.85/hour.
Quoted per deployment. Register your requirement with model sizes, traffic and term, and AxForge scopes the configuration and price with you in EUR, before anything is billed.
With 96 GB of GDDR7 in a Blackwell workstation-class card: large-context inference, fine-tuning small models, and image or video generation.
96 GB of GDDR7, the largest memory in AxForge's RTX tiers.
In an AxForge European region. Dedicated GPU rentals currently run from Málaga, Spain (eu-es-1); placement is confirmed with your request.
Dedicated, with full SSH access. Your model, your traffic, our hardware. Prompts are never persisted. See the privacy policy.
Explore