GPU rental · starter tier
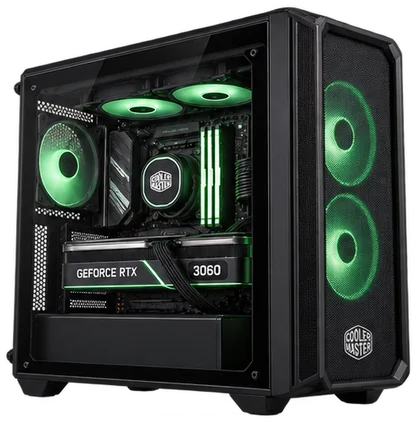
The AxForge starter tier: NVIDIA RTX 3060 cards with 12 GB GDDR6 each in a dedicated machine in Stockholm. Take one card for a 7B to 8B model, embeddings or experiments, or both cards (24 GB for two jobs side by side or one larger model split across them) by the hour, with full SSH access, switched on and off in the console.

Specifications and requirements: Hardware reference.
Specifications
| Configurations | One RTX 3060 (12 GB), or the dual-GPU machine, two cards with 24 GB in total |
|---|---|
| Memory | 12 GB GDDR6 per card |
| Availability | Available, take the next free slot in the console, or reserve a start time |
| Tenancy | Dedicated, your traffic only, full SSH access |
| Price, one card | €0.24/hour on demand |
| Price, both cards | €0.41/hour on demand |
| Longer bookings | from €0.17/hour by the year for one card · from €0.29/hour for both |
| Terms | Per started hour on demand, or a week, month or year at a lower rate |
| Region | Stockholm, Sweden (eu-se-1) |
The pitch: real capacity at the starter price, dedicated to you. If a model needs more than 12 GB per card, look at the DGX Spark with 128 GB of unified memory, or the request-capacity systems: RTX 3090, RTX 5090 and the RTX 6000 Pro.
Community data
On the same-workload llama.cpp CUDA scoreboard the RTX 3060 decodes at 75.6 t/s with 2,138 t/s prompt processing, the baseline of the GPU ladder. That is a 7B to 8B model quantized, embeddings, a dev or test node, or an experiment that should not tie up a bigger machine. Both cards together run two jobs side by side, or one model split across them for 24 GB of room. They are still two 12 GB cards joined over PCIe, so a single request does not get twice as fast.
Which models fit one card: language models · image models · embedding models, estimated from each model's own files and config.
Same-workload numbers from the llama.cpp CUDA scoreboard (Llama 2 7B Q4_0, tg128, full GPU offload). Community measurements, not ours.
How it runs
| On demand | Pay per started hour you use, and switch the machine on and off in the console |
|---|---|
| Reserved start | Book a start time and the machine is prepared for you |
| Week, month, year | Always on, at a lower hourly rate the longer you book |
| Access | Your SSH key, root on the machine, your software stack |
| Location | eu-se-1 · Stockholm. GPU rentals and bare metal run on our machines in Stockholm (eu-se-1) or Málaga (eu-es-1); the console shows each machine's city. AxForge serverless inference runs in Stockholm. |
Data & privacy
Like every AxForge machine: your model, your traffic, our hardware. Prompts are never persisted. Only request metadata (token counts, timestamps, status) is kept for billing and operations. Full policy at axforge.ai/privacy.
FAQ
Yes, it is the AxForge starter tier. Check availability in the console and take the next free slot, or reserve a start time.
Both. Rent a single RTX 3060 with 12 GB for a 7B to 8B model, embeddings or experiments, or the whole dual-GPU machine with 24 GB in total: two jobs side by side, or one larger model split across both cards.
One card €0.24/hour, both cards €0.41/hour on demand. A week, month or year earns a lower rate: from €0.17/hour by the year for one card. Every price is on the pricing page and in the console.
In Stockholm, Sweden (eu-se-1), where AxForge serverless inference also runs.
No. Your model, your traffic, our hardware. Prompts are never persisted. Only operational metadata is kept for billing and operations. See the privacy policy.
Explore