GPU rental · dedicated hardware
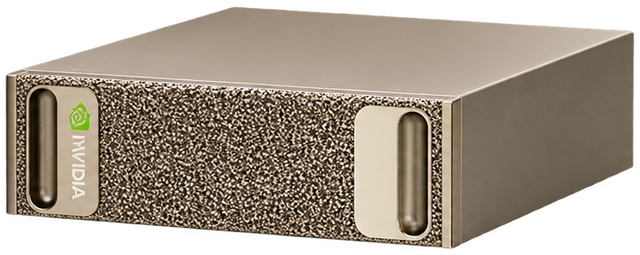
Your own 128 GB GB10 Grace-Blackwell machine with full SSH access, hosted by AxForge in Málaga, Spain (eu-es-1). Rent it by the hour, week, month or year. Take the next available capacity or reserve a start time in advance. Your model, your traffic, your machine.

Specifications
| System | NVIDIA DGX Spark, dedicated, single-tenant |
|---|---|
| Superchip | NVIDIA GB10 Grace-Blackwell, see the GB10 page |
| Memory | 128 GB unified, shared CPU/GPU |
| CPU architecture | ARM64 |
| Access | Full SSH access: your own environment, containers and serving stack |
| Tenancy | Dedicated: the machine is yours for the duration of the rental, not shared capacity |
| Rental term | Hour, week, month or year |
| Pricing | €1.19/hour on demand · €0.95/hour by the week · €0.91/hour by the month · €0.85/hour by the year |
| Availability | Check current availability in the AxForge Console or reserve the next available start time. |
| Region | Málaga, Spain (eu-es-1) |
| Trial | Trial access is available for qualifying customers. |
Performance
| Example workload | Model | Community benchmarks* |
|---|---|---|
| Fast agents / reasoning (MoE) | Qwen3.6 35B-A3B · NVFP4 + MTP | up to 86.3 t/s |
| Coding (MoE) | Qwen3-Coder 30B-A3B | ~42 to 61 t/s |
| Dense reasoning | Qwen3.8 27B · NVFP4 + MTP | 25.1 t/s |
| Smaller dense LLM | Qwen3 8B · Q4 | ~42 t/s |
| Large MoE | DeepSeek V4 Flash · 180B, 13B active | ~23 t/s |
*Community results (SparkBench PBM @ 4k, llama.cpp), labelled, not ours; they vary by runtime, quantization, context length and serving configuration. Full tables, sources and the MoE-vs-dense story on the GB10 page. The same hardware also serves image generation and editing. See the model catalogue.
Which models fit its memory (about 100 GB of the 128 GB is for the model): language models · image models · video models, estimated from each model's own files and config.
Fit
| Use case | Why it fits |
|---|---|
| Dedicated inference, ~7B to 35B models | 128 GB unified memory holds model weights and KV cache in one pool, and the community numbers above are exactly this workload. |
| Private inference | A single-tenant machine in an EU region. Your model, your traffic, our hardware. Prompts are never persisted. |
| Dev / staging nodes | A machine you keep for the day, week or month, a stable target for integration, load testing and pre-production serving. |
| Model evaluation | Run bake-offs on the exact hardware class you would serve from, with results that transfer. |
| AI agents | Host agent runtimes next to their model, long-running processes with no per-token surprise from a third party. |
| Fine-tuning experiments | The unified memory pool fits adapters and smaller fine-tunes that would need careful sharding elsewhere. |
| Self-managed serving & containers | Bring your own serving stack, like vLLM, llama.cpp or custom containers, and run it your way on your machine. |
Searching for DGX Spark cloud or DGX Spark hosting? Same machine: you rent a dedicated physical system, we host and operate it, you reach it over the network.
ARM64
The GB10 platform is ARM64, not x86. Most modern AI frameworks and container images ship ARM64 builds, and our own production serving stack runs on it. x86-only binaries need ARM64 builds or rebuilds. Not sure about your stack? An engineer can review it with you before you commit.
How it works
| 1 | Sign in to AxForge. |
|---|---|
| 2 | Choose your rental duration. Hour, week, month or year. |
| 3 | Check or reserve available capacity. Take the next available machine or schedule a start time. |
| 4 | Add your SSH key. |
| 5 | Connect to your dedicated machine and deploy your models, containers and tools. |
| 6 | End the rental when your workload is complete. |
Check availability or Reserve capacity in the console. Trial access is available for qualifying customers.
Data & privacy
Prompts never persisted. Requests to your dedicated DGX Spark are processed on your own machine in Málaga, Spain (eu-es-1), not logged, not retained and never used by AxForge to train anything. We keep only operational metadata (rental period, machine status) for billing and operations. Full policy at axforge.ai/privacy.
FAQ
Check the live availability in the console. Immediate and scheduled capacity are both supported. Check availability.
Reserve capacity, add your SSH key and receive access to your allocated system for the booked period. From there you deploy your own models, containers and tools, and end the rental when your workload is complete.
€1.19/hour on demand · €0.95/hour by the week · €0.91/hour by the month · €0.85/hour by the year for a dedicated machine. Choose the rental period that fits your workload. Longer reservations receive a lower effective compute rate. Full list on the pricing page.
Anything that fits a 128 GB ARM64 machine you fully control: dedicated inference of ~7B to 35B models, agents, fine-tuning experiments, evaluation, dev/staging, and your own serving stack in containers. If you only need per-token inference, the serverless Qwen API may be enough, no machine required.
Dense models of roughly 7B to 35B, and MoE models far larger: community benchmarks run 80B to 180B MoE at usable speeds, because only the active experts are read per token. Full tables and sources on the GB10 page.
On AxForge you rent a dedicated physical machine, hosted and operated by us in Málaga, Spain (eu-es-1), reachable over the network like any cloud endpoint, but it is your dedicated system, not a shared cloud instance.
The GB10 platform is ARM64. Most modern AI frameworks and container images ship ARM64 builds, and our own serving stack runs on it in production. x86-only binaries need ARM64 builds; an engineer can review your stack before you commit.
Trial access is available for qualifying customers. Request trial access from the console.
No. Your model, your traffic, your dedicated machine. Prompts are never persisted by AxForge. Only operational metadata is kept for billing and operations. See the privacy policy.
Explore