GPU rental · request capacity
Systems with four NVIDIA RTX 5090 cards, 32 GB GDDR7 each, as dedicated EU-hosted AxForge machines. Request dedicated capacity for this GPU through AxForge. Registered demand is used to prioritize new capacity.

Specifications
| System | Four NVIDIA RTX 5090 cards in one dedicated machine |
|---|---|
| Memory | 32 GB GDDR7 per card |
| Availability | Available: register your requirement in the console |
| Tenancy | Dedicated machine, your traffic only, full SSH access |
| Pricing | Quoted per deployment |
| Region | European region, placement confirmed with your request |
Four cards in one box: run one model per card, or spread a workload across the system. An engineer can help map your models onto the machine when you request capacity.
Community data
On the same-workload llama.cpp CUDA scoreboard the RTX 5090 decodes at 290.0 t/s with 14,073 t/s prompt processing, the fastest single-stream result on the board, edging even the 96 GB RTX 6000 Pro (274.2 t/s) when the model fits in 32 GB. Roughly 3.8× an RTX 3060, not 10×: the expensive cards earn their keep on capacity and batch throughput, not just one user's tokens.
Same-workload numbers from the llama.cpp CUDA scoreboard (Llama 2 7B Q4_0, tg128, full GPU offload). Community measurements, not ours. Full ladder on the GPU catalogue.
Community data
Measured by Hardware Corner with llama.cpp at 4k context, one RTX 5090:
| Model | Quant | Decode @ 4k |
|---|---|---|
| Qwen3 30B-A3B MoE | Q4 | 226.1 t/s |
| Qwen3 8B | Q4 | 200.4 t/s |
| Gemma 4 26B | Q4 | 180.3 t/s |
| Qwen3.5 35B MoE | MXFP4 | 165.2 t/s |
| Qwen3 14B | Q4 | 123.8 t/s |
| Qwen3 32B dense | Q4 | 61.4 t/s |
| Qwen3.5 27B dense | Q4 | 58.8 t/s |
MoE vs dense, again
226 t/s for a 30B MoE vs 61 t/s for a 32B dense. Same lesson as GB10: active parameters and memory traffic beat headline parameter count.
Software moves the numbers
A newer llama.cpp run of the same 30B MoE reaches 365.7 t/s on a short tg128 profile. It's a different benchmark shape, so we don't mix it into the table, but it shows how far the serving stack moves the result.
Numbers above are single-card, single-stream. Rent one card or a multi-GPU system, as your workload needs. Community measurements, not ours.
Data & privacy
Like every AxForge machine: your model, your traffic, our hardware. Prompts are never persisted. Only request metadata (token counts, timestamps, status) is kept for billing and operations. Full policy at axforge.ai/privacy.
Models
Estimated from each model's own files and config (32 GB per card): language models · image models · video models · embedding models.
FAQ
Request dedicated capacity for this GPU through the AxForge Console: Ask for this GPU. Registered demand is used to prioritize new capacity, and machines are sized to the workloads that asked for them. Dedicated DGX Spark (GB10) capacity is available now from €0.85/hour.
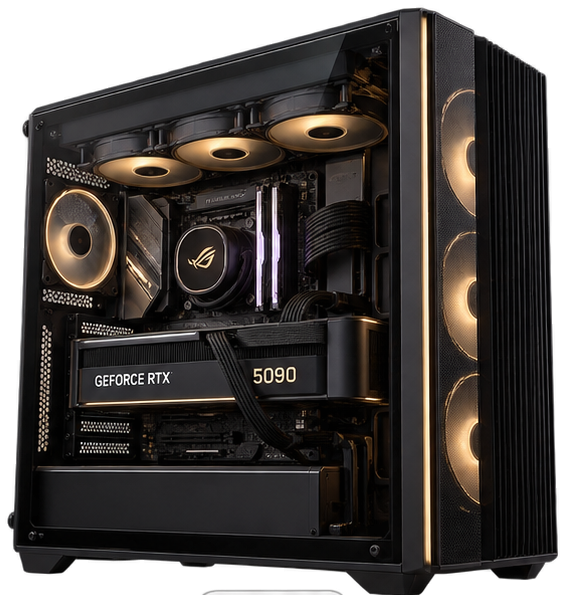
Four NVIDIA RTX 5090 cards with 32 GB GDDR7 each, rented as one dedicated machine serving only your traffic.
Quoted per deployment for the dedicated 4-GPU system. Register your requirement with model sizes, traffic and term, and AxForge scopes the configuration and price with you in EUR, before anything is billed.
In an AxForge European region. Dedicated GPU rentals currently run from Málaga, Spain (eu-es-1); placement is confirmed with your request.
No. Your model, your traffic, our hardware. Prompts are never persisted. Only operational metadata is kept for billing and operations. See the privacy policy.
Explore